26 de out. de 2026 · Victor Slompo
A 10-year-old model beat two frontier LLMs. Same task.
Skin cancer diagnosis. 200 biopsy-proven lesions.
WHAT HAPPENED
A dermatologist tested two frontier LLMs against an old CNN
Dr Magnus Lynch gave 200 biopsy-proven lesions to two frontier LLMs and to Inception v3, a CNN from 2015. The CNN was fine-tuned for about twenty minutes on public dermatology images. All three picked from the same six diagnoses.
THE NUMBER
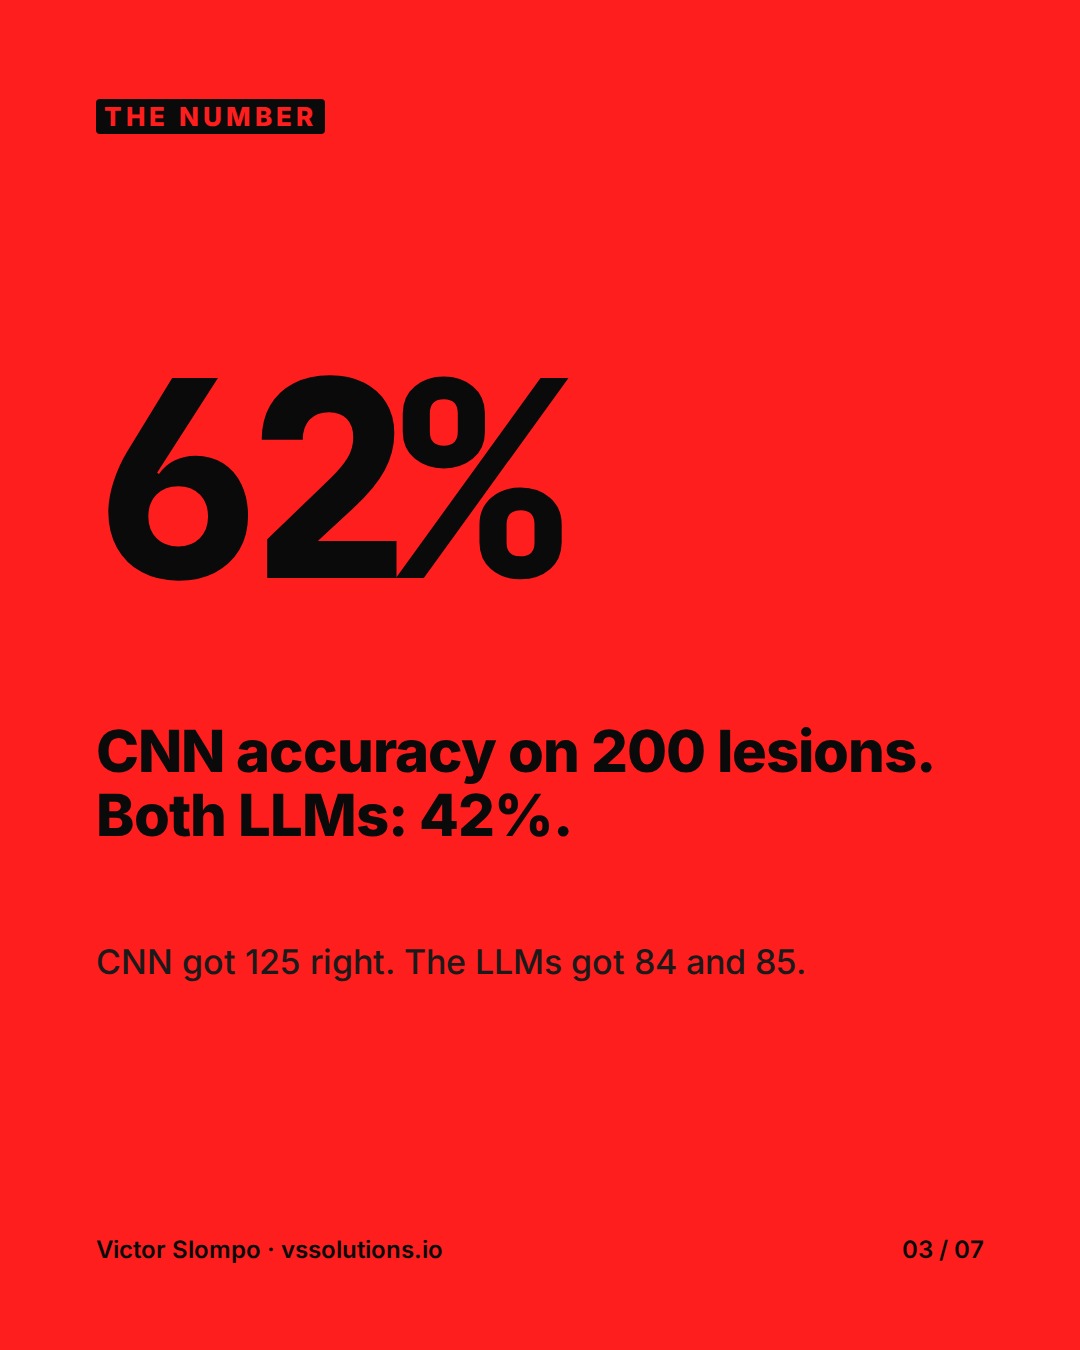
62%
CNN accuracy on 200 lesions. Both LLMs: 42%.
CNN got 125 right. The LLMs got 84 and 85.
THE REAL PROBLEM IN COMPANIES
What I see in companies: the biggest model is the default
- 01Teams pick a frontier LLM first because it is the famous option.
- 02Nobody tests a small, purpose-built model against the same task.
- 03Without a shared baseline, no one can say which option is better.
WHERE THIS BREAKS IN PRACTICE
The result has limits, and the author says so
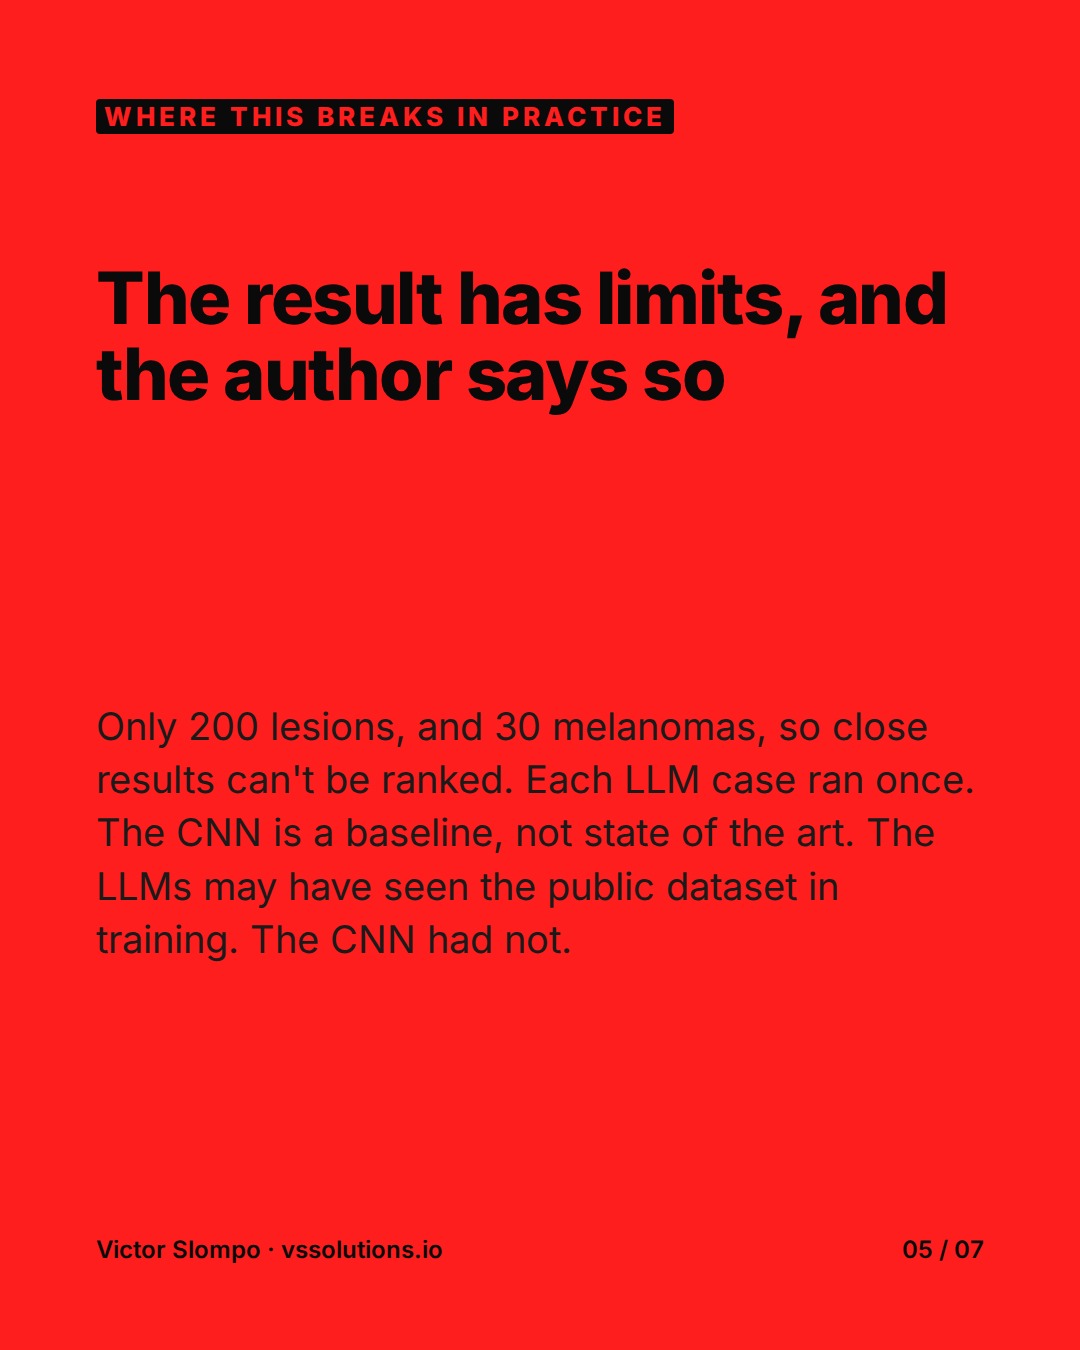
Only 200 lesions, and 30 melanomas, so close results can't be ranked. Each LLM case ran once. The CNN is a baseline, not state of the art. The LLMs may have seen the public dataset in training. The CNN had not.
MY TAKE
Measure instead of assuming.
The study didn't assume the newest model would win. It put three models on the same cases and scored them against the truth. Before you buy a frontier LLM, test a small model on your task. Compare both on the same baseline.
Fontes
Quer isso funcionando na sua empresa?
Eu tiro IA do papel e coloco em produção, com resultado medido. No Instagram, comenta PROJECT no post e eu te mando o passo a passo no direct.