27 de out. de 2026 · Victor Slompo
The agent finished the task. The harness still failed.
A new benchmark separates task success from reliability.
WHAT HAPPENED
A paper scores the harness, not just the model
TraceTrial-Bench evaluates agent performance and harness reliability separately. It covers seven components: context, execution, governance, lifecycle, observability, tools and verification. It ran 4 harnesses, 9 models and 3,420 runs.
THE NUMBER
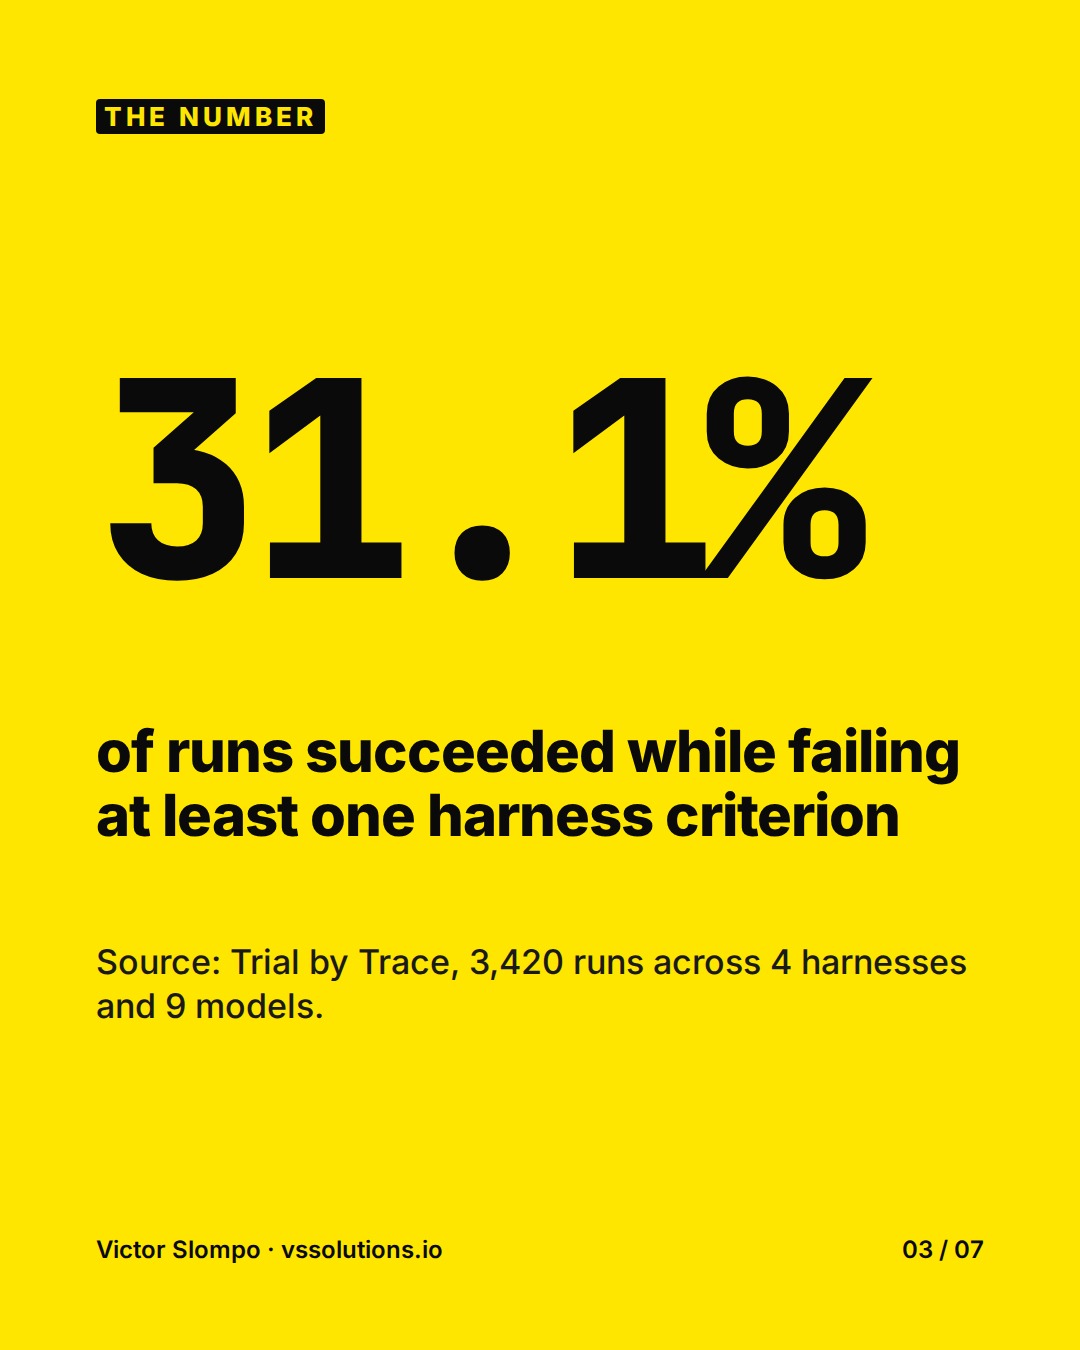
31.1%
of runs succeeded while failing at least one harness criterion
Source: Trial by Trace, 3,420 runs across 4 harnesses and 9 models.
THE REAL PROBLEM IN COMPANIES
What I see in companies: nobody can say where it failed
- 01The demo passes, so the team assumes the agent is reliable.
- 02Tool calls, retries and checks fail silently behind a correct final answer.
- 03Without traces, every incident turns into a debate about the model.
I'VE ALREADY SOLVED THIS
My multi-agent platform at an enterprise account
- 01A multi-agent platform running in production at a US$5.5 million account.
- 02About 60% efficiency gain in production.
- 03Multi-agent in production requires an audited defect log.
MY TAKE
Measure instead of assuming.
A correct final answer does not prove the agent worked. In practice, you need traces that show where each failure happened before you can fix it or trust it. The harness is where that evidence lives, so that is where I look first.
Fontes
Quer isso funcionando na sua empresa?
Eu tiro IA do papel e coloco em produção, com resultado medido. No Instagram, comenta AGENTS no post e eu te mando o passo a passo no direct.