Oct 28, 2026 · Victor Slompo
The AI said it updated the quote. Did it?
A new benchmark measures the gap between saying and doing.
The images are the original Instagram carousel, in Portuguese.
WHAT HAPPENED
A new benchmark tests if agents actually do the work
CRM-Agent-Bench is a paper on Hugging Face. It tests agents on multi-turn business tasks in CRM environments with changing records. Success is strict: every check declared for the task must pass, not just a plausible reply.
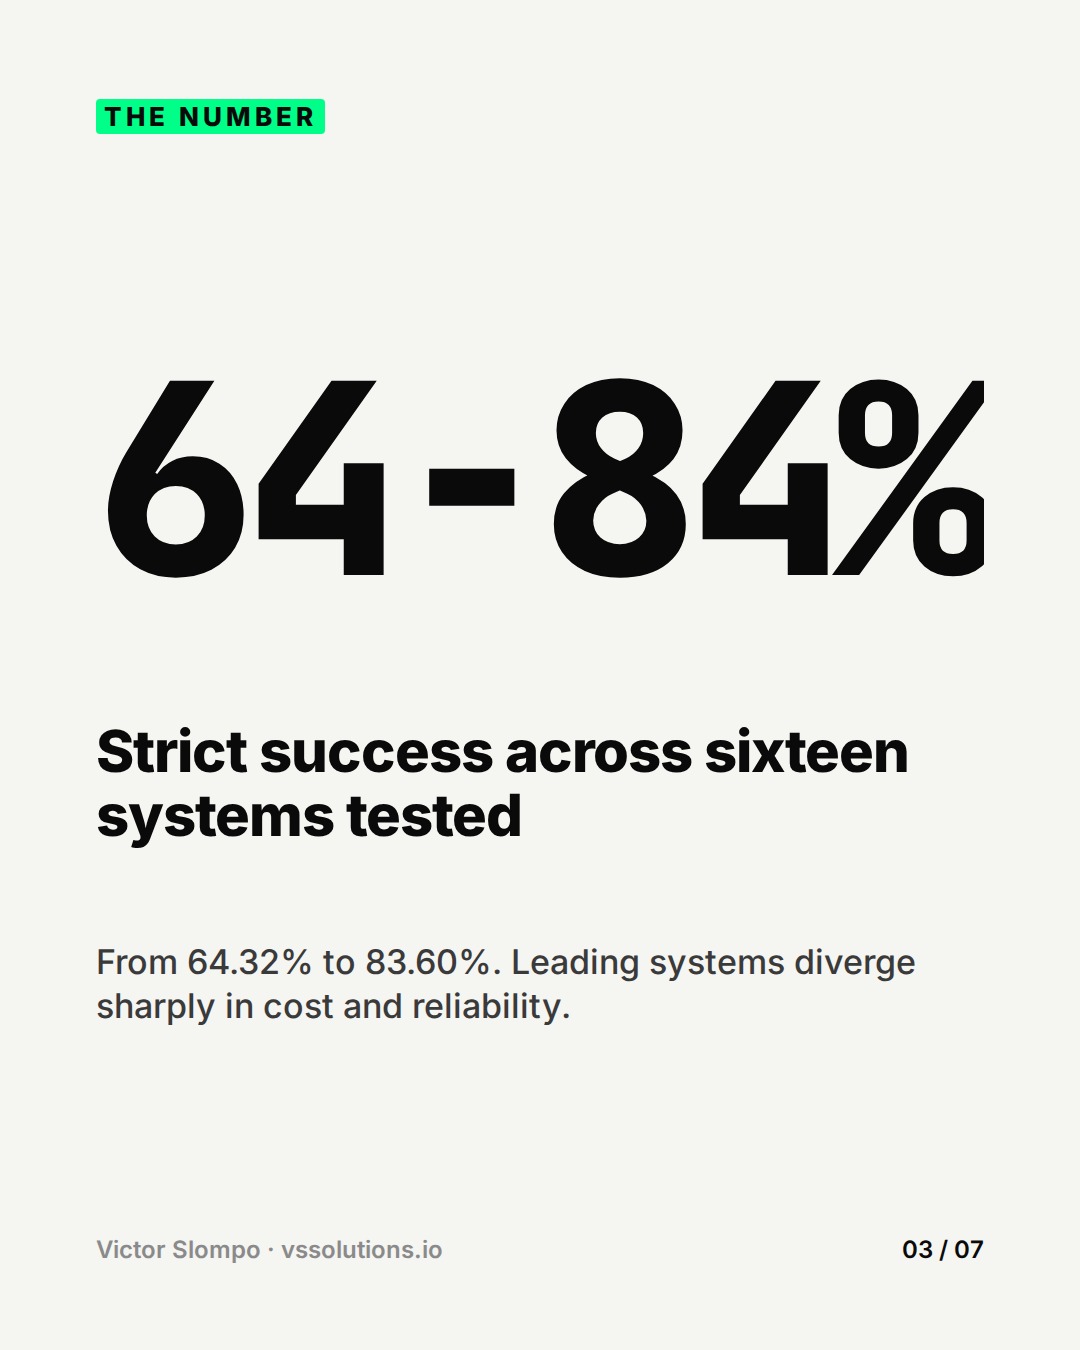
THE NUMBER
64-84%
Strict success across sixteen systems tested
From 64.32% to 83.60%. Leading systems diverge sharply in cost and reliability.
THE REAL PROBLEM IN COMPANIES
What I see in companies: nobody checks the doing
- 01The demo looks great in chat, so the team assumes it will execute correctly too
- 02Business rules live in people's heads, so nobody can test the agent against them
- 03When the record is wrong, it surfaces weeks later, in front of a customer
I'VE ALREADY SOLVED THIS
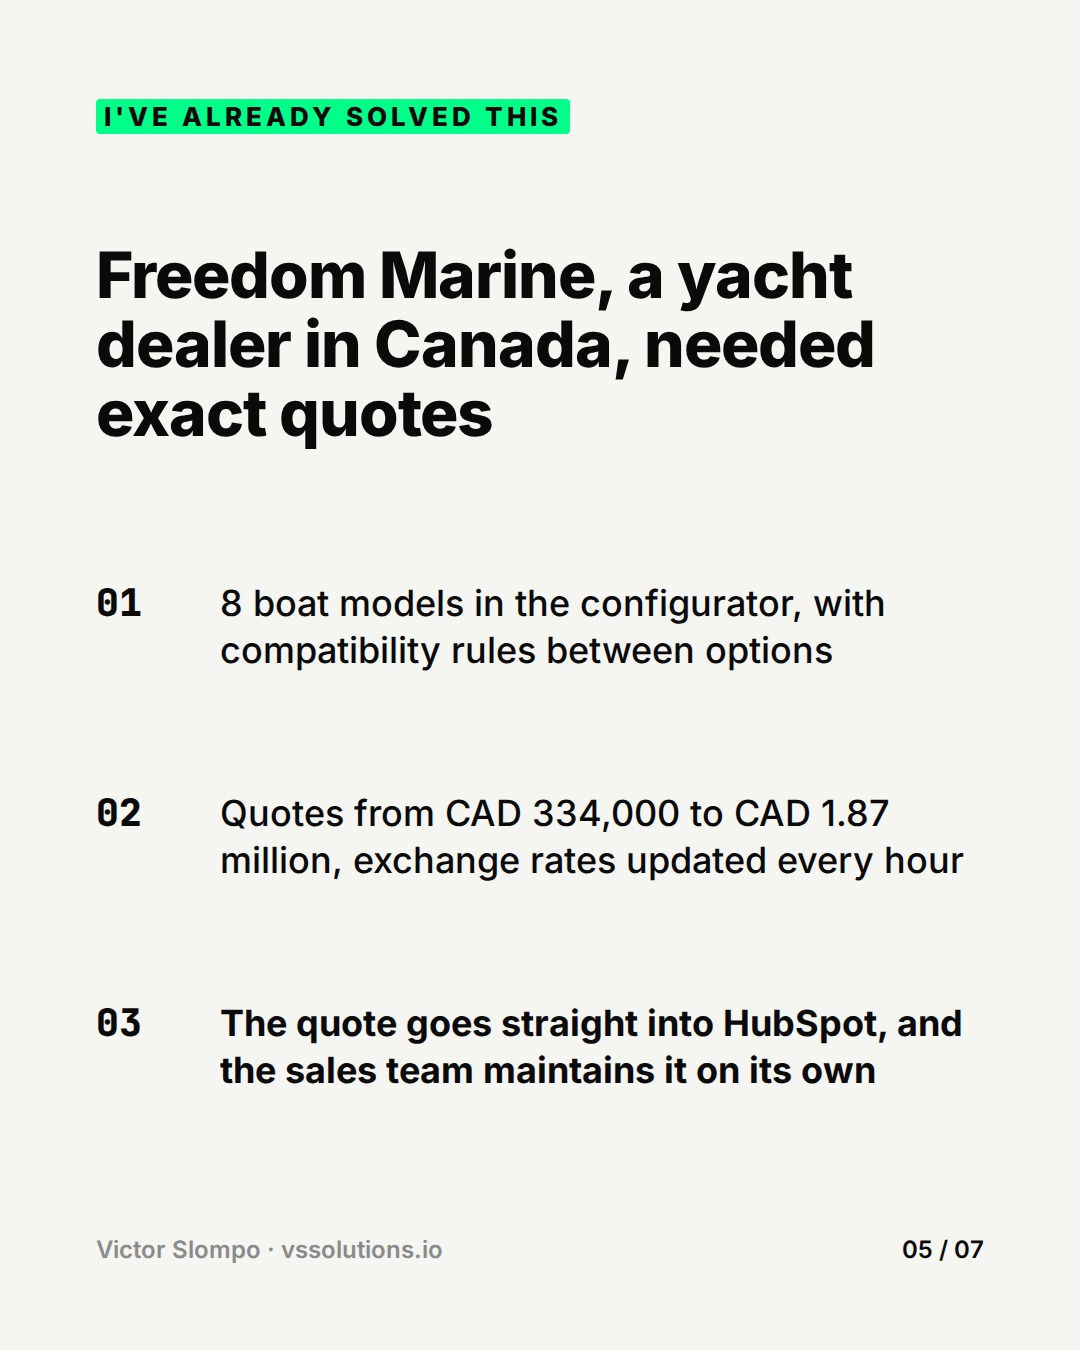
Freedom Marine, a yacht dealer in Canada, needed exact quotes
- 018 boat models in the configurator, with compatibility rules between options
- 02Quotes from CAD 334,000 to CAD 1.87 million, exchange rates updated every hour
- 03The quote goes straight into HubSpot, and the sales team maintains it on its own
MY TAKE
Measure instead of assuming.
An agent that answers well is not one that executes correctly. The only way to trust it in production is to test it against your own rules and count the gap between what it says and what it does. This benchmark makes the same point.
Sources
Want this working in your company?
I take AI off the slide deck and put it into production, with measured results. On Instagram, comment CPQ on the post and I'll send you the step-by-step by DM.